
From Research Protocol to a General AI Reasoning Framework
The methodology developed across this series began with a research problem: how can an AI model help investigate a complex question without simply reinforcing the assumptions already present in the user's prompt?
That problem initially appears to belong to historical or academic research. In reality, it is much broader.
Software debugging, architecture decisions, technical diagnosis, security analysis, product strategy and many forms of decision support share the same underlying structure. A problem is presented. Some evidence is available. One or more explanations appear plausible. Assumptions enter the analysis. The system must determine which conclusion is best supported.
The domain changes. The epistemic problem often does not.
This article therefore takes the next step: converting the research protocol developed in the previous articles into a general reasoning framework for AI-assisted analytical work.
The framework builds directly on four previous layers: Beyond Prompt Engineering: A Methodology for More Reliable AI Reasoning defines the overall methodological problem; The Prompt Is Part of the Bias examines framing and prompt dependency; Prompt Invariance: Does the Conclusion Survive the Prompt? introduces a robustness test against framing; and Falsification for AI Reasoning: From Answers to Tested Hypotheses adds systematic disconfirmation and competing hypotheses.
The Key Generalization
The generalization is not that every task should be treated like historical research.
That would be a category error.
Historical research depends on chronology, provenance, transmission, source criticism and archival completeness. Software debugging depends on logs, configuration, reproducibility, execution state and controlled tests. Architecture depends on requirements, constraints, interfaces, quality attributes and operational trade-offs.
What can be generalized is the reasoning process surrounding those domain-specific forms of evidence.
The framework is domain-independent at its core, but never domain-free.
This distinction is fundamental. A universal reasoning methodology cannot replace expertise. It can instead define how evidence, assumptions, hypotheses, contradictions and uncertainty should be handled before domain expertise produces the final judgment.
A Domain-Independent Reasoning Core
Across analytical domains, the same high-level sequence can be applied:
Problem → decomposition → evidence → assumptions → competing hypotheses → predictions → counter-evidence → discriminating tests → domain validation → confidence recalibration → conclusion
The process deliberately prevents the model's first coherent explanation from becoming the final answer by default.
Instead, the first explanation becomes a candidate.
1. Define the Actual Problem
Before generating a solution, the system should determine what is actually being asked.
User requests frequently contain both a problem and a proposed diagnosis:
Why is nginx causing my API connection failures?
The actual problem may instead be:
What is causing the API connection failures?
The difference is small linguistically and enormous methodologically.
The first formulation embeds a causal hypothesis. The second exposes that hypothesis to competition.
This is precisely the framing problem examined in The Prompt Is Part of the Bias.
2. Separate Facts, Assumptions and Unknowns
A reliable reasoning process must prevent observations and interpretations from silently merging.
- Fact: directly supported by available evidence.
- Interpretation: an explanation inferred from facts.
- Assumption: a proposition required by the current reasoning path but not independently established.
- Unknown: information necessary for stronger discrimination but currently unavailable.
This classification may appear elementary, but it solves a common failure mode in AI-generated analysis: assumptions become embedded in fluent prose and later reappear as if they had already been established.
Traceability begins by preventing inference from disguising itself as evidence.
3. Generate Competing Explanations
A candidate explanation should not be evaluated in isolation when credible alternatives exist.
The system should therefore generate several plausible hypotheses before committing to one.
The purpose is not artificial brainstorming. Alternatives should represent genuinely different mechanisms capable of explaining the observations.
A preferred hypothesis has not won if no serious competitor was allowed to enter the test.
This concept is central to Falsification for AI Reasoning, where hypotheses are evaluated through expected observations, counter-evidence and discriminating tests rather than accumulated supportive prose.
4. Preserve Evidence Provenance
Evidence should remain traceable to its origin.
Conclusion → interpretation → observation → source
A log line, an official technical specification, an experiment, a primary historical document, an expert interpretation and an AI-generated summary do not have identical evidential status.
The framework therefore does not merely store information. It should preserve enough metadata to know where a claim came from and how far the final conclusion is from the original observation.
5. Derive Predictions Before Explaining Results
Once hypotheses exist, each should generate expectations.
If the hypothesis is correct, what should we observe?
If an alternative is correct, what should be different?
Deriving expectations before interpreting all available evidence helps prevent every observation from being retrofitted into the preferred narrative.
6. Search for Counter-Evidence
A generative model is naturally effective at constructing coherent support for a plausible idea. This makes disconfirmation particularly important.
The system should explicitly ask:
- What observation would substantially weaken this explanation?
- What evidence does the hypothesis explain poorly?
- Which alternative explains the same observations with fewer assumptions?
- Which expected observations are missing?
- Could the apparent support be explained by another mechanism?
The principle is developed in detail in Falsification for AI Reasoning: From Answers to Tested Hypotheses.
7. Test Dependence on the Prompt
Evidence testing alone does not reveal whether the model's analysis remains excessively dependent on the user's formulation.
For sufficiently important problems, the conclusion can therefore be retested under alternative legitimate framings.
- Original: preserve the user's formulation.
- Blind: remove the preferred conclusion.
- Inverted: foreground the strongest alternative.
- Adversarial: deliberately search for the strongest evidence-based challenge.
This is the Prompt Invariance method introduced in Prompt Invariance: Does the Conclusion Survive the Prompt?.
Its function is not to prove that a stable answer is true. Its function is to expose conclusions that change primarily because the framing changed.
8. Apply Domain-Specific Validators
This is where the general framework deliberately stops being universal.
Every domain requires its own rules for determining whether an explanation is actually credible.
| Domain | Typical Validators |
| Historical research | Chronology, provenance, geographical plausibility, transmission channels, primary sources, historiography |
| Software debugging | Logs, reproduction, runtime state, configuration, controlled changes, error correlation |
| Software architecture | Requirements, constraints, scalability, maintainability, security, operability, cost |
| Security analysis | Telemetry, attack path, permissions, observable indicators, reproducibility, threat model |
| Product strategy | Customer evidence, pricing behaviour, conversion, alternatives, market constraints, failure criteria |
| Project management | Scope, dependencies, resources, risks, acceptance criteria, milestones, stakeholder constraints |
| Scientific analysis | Experimental design, measurement quality, controls, reproducibility, statistical evidence, alternative explanations |
The framework controls how claims are processed. Domain validators determine whether those claims survive contact with reality.
9. Recalibrate Confidence
The final conclusion should not preserve the confidence level of the initial answer automatically.
Confidence should be recalculated after alternatives, counter-evidence, prompt variation and domain validation have been considered.
A useful output can therefore remain uncertain.
- strongly supported;
- provisionally supported;
- weakly supported;
- underdetermined;
- substantially contradicted;
- not testable with current evidence.
Uncertainty is not a failure of reasoning when the evidence itself is uncertain.
The Same Framework Across Different Domains
The easiest way to understand the general framework is to observe how the same reasoning architecture behaves when the domain changes.
Historical Research
Problem: determine whether similarities between two intellectual traditions indicate historical transmission.
- Separate documented similarities from interpretive parallels.
- Compare direct transmission, indirect inheritance, convergence and retrospective interpretation.
- Test chronology and geographical contact.
- Search for documentary or terminological traces.
- Identify evidence expected under direct transmission.
- Search for earlier independent examples that weaken that hypothesis.
- Reframe the question without the preferred genealogy.
- Conclude only at the confidence level supported by the surviving evidence.
Software Debugging
Problem: determine why an API connection fails intermittently.
- Separate observed failures from the developer's suspected cause.
- Generate proxy, application, database, network and client hypotheses.
- Determine what logs and runtime behaviour each hypothesis predicts.
- Perform tests capable of distinguishing among them.
- Attempt to reproduce the failure while eliminating layers.
- Reject explanations contradicted by controlled observations.
- Identify the first confirmed failure mechanism rather than the most persuasive narrative.
Software Architecture
Problem: choose an architecture for a new platform.
- Separate requirements from implementation preferences.
- Compare modular monolith, services and hybrid alternatives.
- Test each option against scalability, team structure, deployment, operational complexity and cost.
- Identify which requirement genuinely requires architectural complexity.
- Search for simpler designs capable of satisfying the same constraints.
- Treat technology preference as an assumption rather than a requirement.
Product Strategy
Problem: determine whether a product capability should be commercialized.
- Separate technical possibility from demonstrated demand.
- Define alternative customer problems and alternative solutions.
- Identify observable market behaviour predicted by the business thesis.
- Define failure criteria before interpreting results.
- Search for evidence that customers solve the problem differently.
- Distinguish interest, willingness to test and willingness to pay.
Project and Delivery Analysis
Problem: determine why a project is missing planned outcomes.
- Separate symptoms such as delay from their assumed causes.
- Compare scope, dependencies, capacity, requirements, governance and technical risk.
- Trace evidence through plans, decisions, changes and acceptance criteria.
- Test whether corrective action addresses the actual mechanism rather than the visible symptom.
- Reassess the project hypothesis as new delivery evidence appears.
Why This Is More Than Prompt Engineering
Prompt engineering changes the instruction presented to a model.
A reasoning framework changes the process through which an answer is allowed to become a conclusion.
Prompt engineering optimizes an invocation. A reasoning framework governs an inference process.
This difference becomes important as AI systems move from chat interfaces toward agents, RAG pipelines, automated research, development tools and decision-support systems.
A single carefully engineered prompt may improve one model call. A reasoning framework can define how multiple calls, retrieved evidence, tool results and validation stages interact before the system commits to an answer.
The Framework Is Related to — but Different from — Existing LLM Reasoning Methods
The broader research landscape already contains several important approaches showing that LLM performance can improve when inference is structured as a process rather than a single generation.
ReAct combines reasoning with actions and observations from an external environment. Instead of relying exclusively on internal model knowledge, the model can act, observe new information and update its next step.
Self-Refine uses iterative generation, feedback and refinement, demonstrating that an initial LLM output can often be improved through explicit self-feedback without additional model training.
Reflexion uses verbal feedback and episodic memory to allow language agents to learn from previous attempts and modify later behaviour.
Tree of Thoughts explores multiple reasoning paths rather than committing immediately to one left-to-right chain, allowing search, evaluation and backtracking over candidate approaches.
These methods differ substantially in purpose and implementation, but they establish an important general point: inference-time structure can materially change model performance.
The framework proposed in this series addresses a different primary objective.
The goal is not simply to make the model search longer, reflect more or generate a better answer. The goal is to make the path from evidence to conclusion more resistant to framing, confirmation and unsupported assumptions.
Prompt Invariance, falsification-oriented testing and domain-specific validation therefore serve as epistemic controls rather than generic inference-expansion techniques.
A Layered View of AI Reasoning Quality
The resulting system can be understood as several layers.
| Layer | Question |
| Task understanding | What problem are we actually solving? |
| Evidence | What do we actually know? |
| Assumptions | What are we currently taking for granted? |
| Hypotheses | What plausible mechanisms could explain the evidence? |
| Falsification | What evidence could weaken each explanation? |
| Prompt Invariance | Does the conclusion depend excessively on framing? |
| Domain validation | Does the explanation satisfy the rules of the relevant discipline? |
| Confidence calibration | How strongly should the surviving conclusion be trusted? |
An answer can fail at any layer.
It can answer the wrong problem correctly. It can reason correctly from false evidence. It can retrieve correct facts but choose the wrong causal explanation. It can produce a strong explanation that disappears when the prompt is reframed. Or it can survive all general reasoning checks and still violate a domain-specific constraint.
Correctness is not one property. It is the result of several dependencies surviving simultaneously.
Reasoning Quality Versus Model Capability
This leads back to one of the central ideas of the series.
A stronger model does not automatically imply that every invocation will use its capabilities in the most rigorous possible way.
A model may possess the capability to generate alternatives, inspect logs, search sources, challenge assumptions and revise a conclusion. Whether all of those operations actually occur depends on the task, prompting, available tools, context and surrounding system architecture.
The framework therefore separates two questions:
- Capability: what can the model do?
- Methodological discipline: which of those capabilities must be exercised before the system accepts a conclusion?
The distinction was the starting point of Beyond Prompt Engineering and becomes even more important once the methodology is generalized beyond research.
Not Every Task Needs the Full Framework
The framework should not become compulsory overhead for every AI interaction.
Many tasks have low epistemic complexity:
- format this JSON;
- translate this sentence;
- convert these units;
- rewrite this message;
- extract these fields;
- summarize this supplied text.
Running four prompt variants, three competing hypotheses and a falsification stage for such tasks would add cost without proportional value.
The full method becomes more valuable when:
- the answer depends on interpretation rather than direct retrieval;
- the user already has a preferred explanation;
- multiple causal mechanisms are plausible;
- the evidence is incomplete or contradictory;
- the decision has significant technical, financial or research consequences;
- the AI system is expected to act autonomously on the conclusion.
Methodological depth should therefore scale with epistemic risk.
From Static Prompt to Adaptive Reasoning Policy
Once generalized, the framework no longer needs to exist as one enormous prompt.
A practical system can decide dynamically which controls a task requires.
Simple task → direct answer Analytical task → structured evidence check High-uncertainty task → competing hypotheses Framing-sensitive task → Prompt Invariance High-consequence hypothesis → falsification and domain validation
This transforms the methodology from a fixed prompt template into an adaptive reasoning policy.
The system does not always reason maximally. It reasons as rigorously as the task requires.
A Practical General Framework
The complete process can be summarized as follows:
- Normalize the problem. Remove embedded conclusions from the task definition where appropriate.
- Identify evidence. Separate observations from interpretations.
- Expose assumptions. Record propositions that have not yet been established.
- Generate serious alternatives. Do not allow the first hypothesis to compete only against weak strawmen.
- Preserve provenance. Keep claims traceable to their sources.
- Derive expectations. Define what each hypothesis predicts.
- Search for counter-evidence. Actively look for observations the preferred hypothesis handles poorly.
- Run discriminating tests. Prefer evidence that differentiates among explanations.
- Test framing dependence. Apply Prompt Invariance when the user's framing may influence the result.
- Apply domain validators. Use the discipline-specific criteria relevant to the problem.
- Recalibrate confidence. Allow the conclusion to weaken, remain unresolved or change.
- Preserve traceability. Make the path from conclusion back to evidence inspectable.
What the Framework Does Not Claim
- It does not guarantee truthful output.
- It does not eliminate hallucinations.
- It does not make an LLM a domain expert.
- It does not prove that stable conclusions are correct.
- It does not eliminate biases shared across all reasoning passes.
- It does not replace experiments, measurements or primary sources.
- It does not guarantee that all relevant hypotheses have been generated.
- It does not imply that more reasoning is always better.
- It does not claim that the complete framework has already been validated as a standardized academic methodology.
Its claim is narrower and more defensible: analytical AI systems can be made methodologically stronger when assumptions, framing, competing explanations, counter-evidence and domain validation are handled explicitly rather than left entirely to one unconstrained generation.
The Four Articles Become One Reasoning System
The previous articles can now be understood not as separate prompting techniques but as components of one reasoning architecture.
| Article | Function in the Framework |
| Beyond Prompt Engineering | Defines the shift from answer generation to methodological reasoning. |
| The Prompt Is Part of the Bias | Treats the user's formulation as a possible source of reasoning bias. |
| Prompt Invariance | Tests whether the conclusion survives meaningful changes in framing. |
| Falsification for AI Reasoning | Tests whether hypotheses survive disconfirming evidence and serious alternatives. |
| From Research Protocol to a General AI Reasoning Framework | Combines the controls into a domain-independent core with domain-specific validation. |
Together they describe a transition:
Prompt → answer becomes Problem → evidence → hypotheses → challenge → validation → calibrated conclusion
The Central Principle
The methodology began with a simple observation: asking a powerful reasoning model a question does not automatically mean that every useful reasoning capability available to the model will be used.
The solution is not to force maximal reasoning into every interaction.
The solution is to identify which reasoning controls matter for the task and make them explicit.
A good AI methodology does not tell the model what conclusion to reach. It defines what a conclusion must survive before it is accepted.
That principle is transferable.
In historical research, the conclusion must survive chronology and source criticism. In debugging, it must survive reproduction and discriminating tests. In architecture, it must survive requirements and operational constraints. In strategy, it must survive market evidence and failure criteria.
The validators change.
The methodological discipline remains.
The objective is not a model that always thinks longer. It is a system that knows when an answer is not yet justified.
Research Context
The complete framework described in this series is a methodological synthesis rather than an established standardized LLM benchmark. Several adjacent lines of research nevertheless support its central architectural premise: inference quality can change substantially when language-model problem solving is organized as an iterative or multi-stage process rather than a single generation.
ReAct combines reasoning with actions and external observations and demonstrated benefits across question answering, fact verification and interactive decision tasks. Tree of Thoughts explores multiple candidate reasoning paths with evaluation and backtracking rather than committing immediately to one chain. Self-Refine showed improvements across diverse tasks by iterating between generation, feedback and refinement. Reflexion demonstrated that language agents can use verbal feedback from previous attempts to improve later decisions without updating model weights.
These approaches do not implement Prompt Invariance or the falsification-oriented framework proposed here. They provide independent evidence for the broader idea that inference-time procedure matters: model capability and the process through which that capability is exercised are not identical.
The contribution of this series is to organize that insight around epistemic controls: evidence separation, assumption tracking, prompt-framing analysis, competing hypotheses, falsification, provenance, domain validation and calibrated uncertainty.
Selected References
- Yao, S. et al. — ReAct: Synergizing Reasoning and Acting in Language Models. ICLR, 2023.
- Yao, S. et al. — Tree of Thoughts: Deliberate Problem Solving with Large Language Models. NeurIPS, 2023.
- Madaan, A. et al. — Self-Refine: Iterative Refinement with Self-Feedback. NeurIPS, 2023.
- Shinn, N. et al. — Reflexion: Language Agents with Verbal Reinforcement Learning. NeurIPS, 2023.
- Jhaveri, A. R., GX-Chen, A., Sucholutsky, I. & Choi, E. — Failing to Falsify: Evaluating and Mitigating Confirmation Bias in Language Models. 2026.
- Brucks, M. S. & Toubia, O. — Prompt Architecture Induces Methodological Artifacts in Large Language Models. PLOS ONE, 2025.
The AI Reasoning Methodology Series
- Beyond Prompt Engineering: A Methodology for More Reliable AI Reasoning — why model capability alone is not enough.
- The Prompt Is Part of the Bias — how task formulation can influence the reasoning environment.
- Prompt Invariance: Does the Conclusion Survive the Prompt? — testing conclusion stability across alternative framings.
- Falsification for AI Reasoning: From Answers to Tested Hypotheses — competing hypotheses, counter-evidence and discriminating tests.
- From Research Protocol to a General AI Reasoning Framework — integrating the methodology into a reusable domain-independent reasoning core.
- A practical application of the same reasoning framework in gaming AI — including game assistants, autonomous agents, patch-sensitive knowledge and live game-state validation — is explored in When Gaming AI Sounds Right but Isn't: The Reasoning Problem Behind Game Assistants and Agents on figure.rocks.
Related Articles
Canonical Architecture, URL Design, Resolver Logic, API & Scalability Specification
Geo-based discovery architecture for multi-tenant portals. Defines canonical URLs, resolver logic, caching strategy, and a geo read-model without CMS coupling or database refactoring. Designed for SEO stability, scalability, and future extensions like booking and maps.
Google I/O 2026: Antigravity, AI Studio, and the Shift to Agentic DevTools
Google I/O 2026 made one thing clear for engineers: AI tooling is moving beyond autocomplete into managed agentic execution. This article breaks down Antigravity 2.0, the expanding role of Google AI Studio, Gemini 3.5 Flash, and the real trade-offs around orchestration, lock-in, verification, and developer workflow design.
Google I/O 2026: Android XR, Intelligent Eyewear, and the Ambient AI Interface
Google I/O 2026 pushed Android XR and intelligent eyewear from concept toward a real platform direction. This article breaks down audio glasses, display glasses, Gemini-powered context awareness, developer implications, privacy risks, and why wearable AI is less about replacing phones and more about creating ambient assistance surfaces.
mozilla-thunderbird-68-x-kann-oauth2-fuer-provider-for-google-calendar-nicht-speichern
A Practical Monorepo Architecture with Next.js, Fastify, Prisma, and NGINX
Explore a practical monorepo architecture using Next.js, Fastify, Prisma, and NGINX, highlighting real-world integration and workflow.
Enterprise Start Here: Your Gateway to Operational Excellence
New to our enterprise platform? This guide provides a structured onboarding path, from foundational reference models to actionable playbooks, runbooks, and assessments designed for seamless implementation.
Comprehensive Guide to Test Dev Enterprise Stajic.de: Architecture and Best Practices
Explore the architectural principles, benefits, and technical details of managing an enterprise-grade development and testing environment with Test DEv Enterprise Stajic.de.
PostfixAdmin: Enterprise-Grade Management for Postfix Mail Systems — Anno 2026
PostfixAdmin is a database-centric administration interface designed for professional Postfix mail systems. Rather than hiding complexity, it provides precise control over domains, mailboxes, aliases, and sender permissions. This article explains why PostfixAdmin remains a trusted enterprise solution in 2026 and how it fits into modern, security-focused mail infrastructures.
Qwen 3.6 in Production: Release Runbook, AI Rollback, and LLMOps Versioning
Qwen 3.6 is not just another model upgrade. It is a release event, a rollback scenario, and a versioning problem at the same time. This article explains how Qwen 3.6 should be handled in production through LLMOps discipline, prompt and model traceability, controlled rollout, and evidence-based rollback readiness.
Google I/O 2026: Architectural Pivots, Agentic AI, and the Unified Ecosystem Reality Check
Google I/O 2026 was not just a model event. It showed a deeper platform shift across Gemini models, developer tooling, Android-linked surfaces, and intelligent devices. This article breaks down the keynote as a hub story for engineers, architects, and product teams who need to separate real runtime implications from stage-level hype.
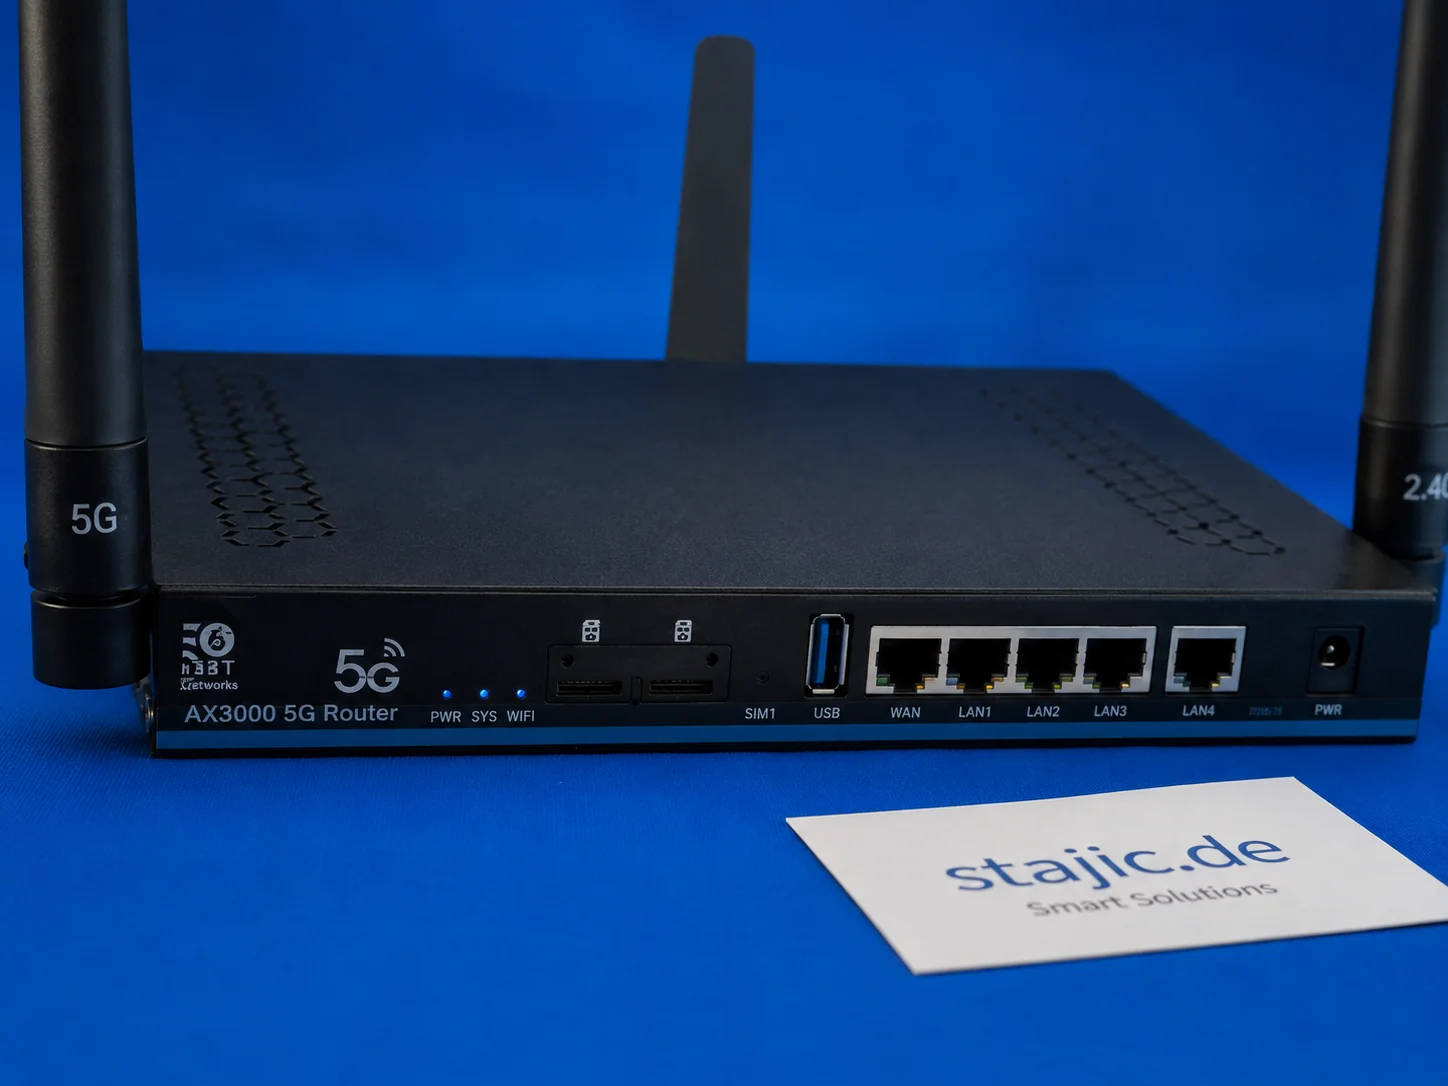
Quectel RM500U-EA in the ZBT Z8102AX: 5G Bands, o2 Germany and Real-World Signal Behavior
The ZBT Z8102AX uses a Quectel RM500U-EA modem for 4G and 5G connectivity. In the first practical test, the router connected successfully to o2 Germany with LTE Band 3 and NR n28. The modem works, but deeper diagnostics such as RSRP, RSRQ, SINR, band locking and cell behavior still need proper testing.