
Beyond Prompt Engineering: A Methodology for More Reliable AI Reasoning
Prompt engineering is usually treated as the art of asking a model better questions. That is useful, but it addresses only part of the problem. A well-written prompt can improve relevance, structure and task compliance without making the resulting conclusion epistemically robust.
The deeper problem is that a large language model does not reason independently of the prompt that activates it. Wording, framing, ordering, assumptions embedded in the request and the user's explicitly stated position can all influence which parts of the model's internal knowledge become dominant in the generated answer.
This means that improving AI reasoning requires more than better instructions. It requires a methodology that treats the prompt itself as a potential source of bias and subjects the model's conclusion to structured verification.
The objective is not to make the model more intelligent. The objective is to use the intelligence already available to it more rigorously.
Capability Is Not the Same as Reasoning Discipline
Modern reasoning models can decompose complex tasks, compare alternatives, inspect evidence, identify contradictions and revise conclusions. But having these capabilities does not imply that every response will automatically use all of them.
A general-purpose AI assistant has to operate across radically different tasks and users. One user wants a calculation. Another wants a short message rewritten. Another wants software debugging. Another expects a historical or scientific investigation. Applying a maximal hypothesis-testing protocol to every request would frequently increase latency, verbosity and cognitive overhead without improving the actual usefulness of the answer.
Consequently, the central question is not simply whether a model can perform rigorous reasoning. The more important question is under which conditions that capability is systematically activated, challenged and verified.
The Prompt Is Not a Neutral Interface
Research has repeatedly shown that apparently secondary characteristics of prompts can influence model outputs. Prompt order, labels, framing and requests for justification have all been demonstrated to produce measurable methodological artifacts. Separate research on sycophancy has shown that language models may sometimes adapt their answers toward positions expressed by the user rather than maintaining an entirely independent evaluation.
This does not mean that every model merely agrees with its user, nor that every prompt contaminates every conclusion. It means something more precise: the prompt forms part of the inference environment. Therefore, a conclusion obtained under one framing cannot automatically be assumed to be invariant under another.
The consequences of that distinction are examined separately in The Prompt Is Part of the Bias, where prompt framing, instruction following and model agreement behaviour are treated as a methodological problem rather than merely a prompting problem.
From Prompt Engineering to an Epistemic Process
Traditional prompt engineering primarily optimizes the input. The methodology proposed here instead structures the complete path from question to conclusion.
A simplified form of that process can be represented as:
Problem → decomposition → evidence → competing hypotheses → counter-evidence → falsification attempts → synthesis → framing check → calibrated conclusion
The important difference is that the first coherent answer is no longer treated as the endpoint. It becomes a candidate conclusion that must survive additional tests.
1. Separate Evidence from Interpretation
The first requirement is to prevent observations, interpretations and assumptions from collapsing into one narrative. A model should explicitly distinguish what is directly supported from what is inferred.
- Evidence: information directly supported by a source, observation, measurement, log, document or reproducible result.
- Interpretation: an explanation derived from the evidence.
- Assumption: a proposition currently required by the reasoning process but not yet independently established.
- Open question: a relevant uncertainty for which the available evidence is insufficient.
This separation is simple, but it has an important consequence: uncertainty becomes visible before it is absorbed into the final narrative.
2. Generate Competing Hypotheses
A strong explanation is not established merely because evidence can be interpreted in its favour. The model should construct credible alternatives and ask whether the same evidence can also be explained by them.
In historical research, this might mean distinguishing direct transmission, indirect transmission, independent convergence and retrospective interpretation. In software debugging it may mean separating a network failure, configuration error, application bug and external service failure. In business analysis it may mean comparing multiple causal explanations for the same market signal.
The labels change across disciplines. The methodological principle does not.
3. Search for Evidence That Could Make the Preferred Explanation Fail
Confirmation is comparatively easy. Given a plausible hypothesis, both humans and language models can often find facts that appear compatible with it. A more demanding test asks what evidence should exist if the hypothesis were true, what evidence should not exist, and which observation would significantly weaken it.
Recent experimental work on confirmation bias in language models supports the importance of this step. When models are allowed to test hypotheses freely, they can prefer confirmatory tests over falsifying ones. Explicit interventions that encourage counterexamples and disconfirming tests have been shown to improve hypothesis discovery.
The full role of falsification and counter-evidence in this methodology is developed in Falsification for AI Reasoning: From Answers to Tested Hypotheses.
4. Preserve Provenance and Causal Distance
Not all supporting information has equal evidential value. A primary document, a secondary interpretation, a later quotation, an unsourced summary and a model-generated paraphrase cannot be treated as interchangeable merely because they contain similar claims.
A rigorous process therefore preserves the path between source and conclusion. Where possible, the reasoning chain should remain inspectable:
Conclusion → interpretation → supporting evidence → source
Domain-specific validators can then be added. Historical research requires chronology, geographical plausibility, provenance and possible transmission channels. Software architecture requires constraints, compatibility, performance, maintainability and failure modes. Scientific analysis requires experimental design, measurement quality, reproducibility and alternative causal explanations.
5. Test Whether the Conclusion Survives the Prompt
The most important extension is to treat the prompt itself as a variable.
I use the term prompt invariance here for a practical test: does the essential conclusion remain stable when the same evidence is examined under materially different but legitimate prompt framings?
A useful implementation can contain at least four passes:
- Original pass: analyze the problem as initially formulated.
- Blind pass: remove the user's preferred explanation and ask which hypothesis the evidence supports.
- Inverted pass: treat a credible opposing hypothesis as the starting proposition and test it against the same evidence.
- Adversarial pass: deliberately construct the strongest evidence-based challenge to the current conclusion.
The objective is not to force four identical answers. Legitimate framing differences may expose previously hidden assumptions. The relevant signal is which factual findings, causal links and confidence judgments survive across the different formulations.
Prompt invariance should therefore not be confused with factual proof. It is better understood as a robustness test against one specific class of methodological dependency: excessive dependence on the original framing.
The concept and its limitations are developed in detail in Prompt Invariance: Does the Conclusion Survive the Prompt?.
6. Calibrate the Conclusion Instead of Forcing Certainty
A methodology designed to resist confirmation bias must allow the final state to remain uncertain. The process has failed if every investigation is required to end in a confident yes or no.
Possible outcomes include strong support, moderate support, weak support, unresolved competition between hypotheses, insufficient evidence, or evidence inconsistent with the original proposition. The important requirement is that confidence follows the quality and structure of the evidence rather than the rhetorical coherence of the generated answer.
A Domain-Independent Core with Domain-Specific Validators
The methodology originally becomes especially visible in research tasks because research naturally exposes problems of evidence, interpretation and competing explanations. But its core is not restricted to historical or academic work.
The same general structure can be applied to debugging, software architecture, product strategy, technical due diligence, project management, security analysis and other domains in which a plausible first answer can be substantially weaker than a tested conclusion.
What changes is the validation layer. The epistemic core remains largely stable while each domain supplies its own rules for determining what counts as strong evidence, a plausible causal mechanism or a meaningful falsification test.
This transition from a research protocol to a reusable reasoning framework is the subject of From Research Protocol to General AI Reasoning Framework.
Why a Reasoning Model Does Not Automatically Apply the Full Method
It would be tempting to conclude that sufficiently advanced reasoning models should make this methodology unnecessary. That conclusion confuses capability with default behaviour.
A general assistant has no universal reason to maximize epistemic verification for every request. Users differ in expertise, objectives, available time, desired depth and tolerance for complexity. Tasks also differ radically in the cost of being wrong.
For many requests, a direct answer is the correct product behaviour. For others, especially research, architecture, high-impact decisions and complex technical diagnosis, additional verification can substantially improve reliability.
The methodology therefore acts as a deliberate change in the reasoning objective. Instead of optimizing primarily for a useful and coherent response, it gives additional weight to epistemic robustness, traceability and resistance to the user's initial framing.
From Methodology to an Epistemic Verification Layer
Once expressed as a repeatable process, the methodology no longer has to exist only as a long instruction placed in front of a language model. It can become part of an AI architecture.
Different agents or inference passes can generate hypotheses, search for contradictory evidence, evaluate sources, perform adversarial review and compare results across prompt variants. The final answer can then be produced from the verified intermediate state rather than directly from the original user request.
Prompt → decomposition → candidate explanations → evidence → challenge → verification → synthesis → response
This architecture and its relationship to agents, retrieval systems and multi-pass inference are developed in Designing an Epistemic Verification Layer for LLMs.
What This Methodology Does Not Claim
A rigorous methodology should also define its own limits.
- It does not guarantee that the model possesses the necessary knowledge.
- It does not make weak or missing evidence stronger.
- It does not eliminate hallucination, framing effects or model bias.
- It does not prove that a conclusion is true simply because several prompt variants produced it.
- It does not replace domain expertise, primary sources, experiments or external verification where those are required.
- It increases computational work, token usage and latency.
- Its purpose is to make errors, assumptions and dependencies easier to expose before they become conclusions.
The Central Principle
Prompt engineering asks how to obtain a better answer from a model.
The methodology described here asks a different question:
What process should an AI conclusion survive before we decide that the answer is good enough to trust?
That change of perspective is fundamental. It moves the focus away from optimizing a single prompt and toward controlling the reasoning process around it.
The prompt remains important, but it is no longer treated as an unquestioned starting point. It becomes one input into a process that can inspect its assumptions, challenge its framing and test whether the resulting conclusion survives alternative interpretations.
In practical terms, the methodology does not attempt to create a smarter model. It attempts to create a more disciplined use of the model's existing capabilities.
Research Context
The methodological proposal in this article is informed by several related areas of current LLM research. Sharma et al. examined sycophantic behaviour in AI assistants and the relationship between human preference signals and agreement with user beliefs. Brucks and Toubia demonstrated that prompt architecture — including order, labels, framing and justification — can create systematic methodological artifacts in model responses. Jhaveri et al. experimentally examined confirmation bias during hypothesis exploration and found that interventions encouraging counterexamples reduced confirmatory behaviour and improved rule discovery.
These studies do not establish the complete methodology proposed here, nor do they constitute evidence that prompt invariance is a standardized validation metric. They establish narrower empirical findings that motivate the need for more explicit control over framing, hypothesis testing and verification.
Selected References
- Sharma, M. et al. — Towards Understanding Sycophancy in Language Models. arXiv:2310.13548, originally published 2023; revised 2025.
- Brucks, M. S. & Toubia, O. — Prompt architecture induces methodological artifacts in large language models. PLOS ONE, 2025.
- Jhaveri, A. R., GX-Chen, A., Sucholutsky, I. & Choi, E. — Failing to Falsify: Evaluating and Mitigating Confirmation Bias in Language Models. arXiv, 2026.
Continue the Series
- The Prompt Is Part of the Bias — how framing, instructions and user assumptions influence model reasoning.
- Prompt Invariance: Does the Conclusion Survive the Prompt? — a practical robustness test using blind, inverted and adversarial formulations.
- Falsification for AI Reasoning: From Answers to Tested Hypotheses — counter-evidence, competing hypotheses and disconfirming tests.
- From Research Protocol to General AI Reasoning Framework — applying the methodology beyond historical research.
- Gaming AI: Applied Reasoning Under Uncertain Information — an applied perspective from figure.rocks.
Related Articles
Search Engine Optimization: The reliable workflow for Top-Rankings
Detailed analysis of search engine optimization (SEO), its technical foundations, the role of web crawlers, and the strategic steps to achieve organic top rankings.
Google I/O 2026: Agentic Products Across Search, Workspace, and Shopping
Google I/O 2026 showed that agentic AI is moving beyond model demos and developer tools into everyday product surfaces. This article breaks down how Search, Workspace, Gemini Spark, and Universal Cart point toward a new product model where Google agents help users research, work, shop, and act across connected services.
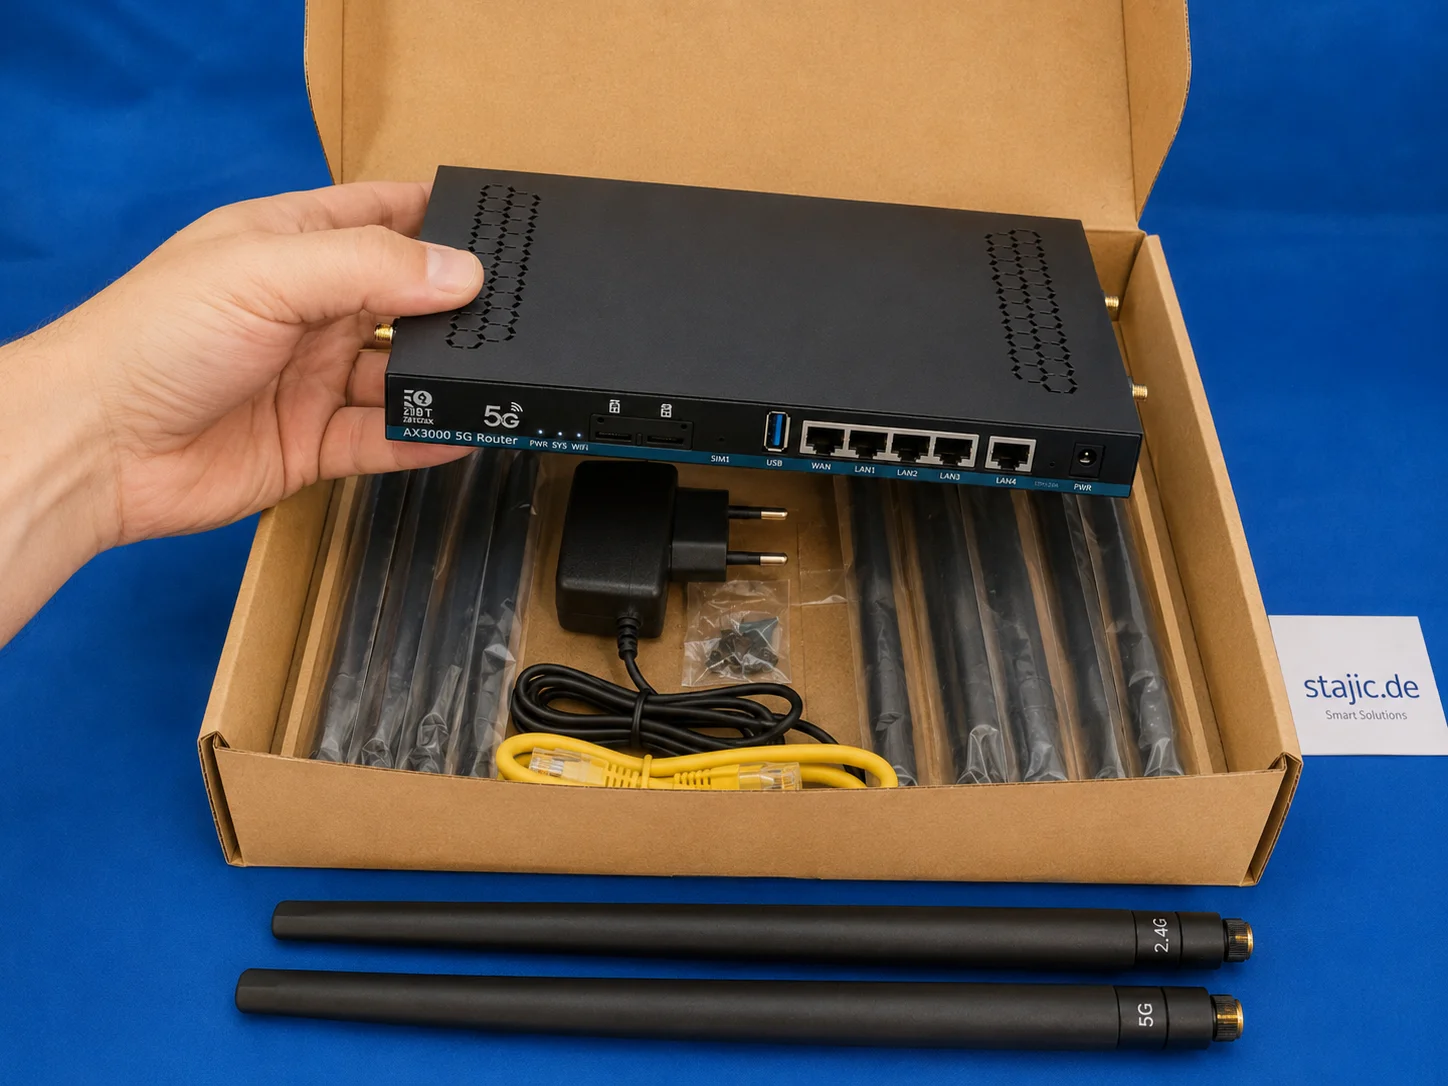
ZBT Z8102AX Hardware and Packaging Review: Strong Router, Weak Box
The ZBT Z8102AX makes a solid first impression as a slim black metal 5G OpenWrt router with multiple antenna connectors, dual-SIM slots, USB, LAN/WAN ports and a practical accessory set. The hardware feels useful and serious, but the packaging is clearly the weak point.
PostfixAdmin: Enterprise-Grade Management for Postfix Mail Systems — Anno 2026
PostfixAdmin is a database-centric administration interface designed for professional Postfix mail systems. Rather than hiding complexity, it provides precise control over domains, mailboxes, aliases, and sender permissions. This article explains why PostfixAdmin remains a trusted enterprise solution in 2026 and how it fits into modern, security-focused mail infrastructures.
Canonical Architecture, URL Design, Resolver Logic, API & Scalability Specification
Geo-based discovery architecture for multi-tenant portals. Defines canonical URLs, resolver logic, caching strategy, and a geo read-model without CMS coupling or database refactoring. Designed for SEO stability, scalability, and future extensions like booking and maps.
Multi-Database Architecture with Prisma 7: A Deep Dive for Experts
The management of complex data landscapes requires modern architectures. Prisma 7 offers advanced functionalities for multi-database integration and addresses the challenges of Polyglot Persistence.
A Practical Monorepo Architecture with Next.js, Fastify, Prisma, and NGINX
Explore a practical monorepo architecture using Next.js, Fastify, Prisma, and NGINX, highlighting real-world integration and workflow.
Qwen 3.6 in Production: Release Runbook, AI Rollback, and LLMOps Versioning
Qwen 3.6 is not just another model upgrade. It is a release event, a rollback scenario, and a versioning problem at the same time. This article explains how Qwen 3.6 should be handled in production through LLMOps discipline, prompt and model traceability, controlled rollout, and evidence-based rollback readiness.
The Prompt Is Part of the Bias: How AI Framing Shapes Reasoning
Prompt wording is not neutral. Explore how framing, assumptions, instruction-following and sycophancy can shape AI reasoning—and why reliable conclusions require testing beyond the original prompt.
Prompt Invariance: Does the Conclusion Survive the Prompt?
A practical methodology for testing whether an AI conclusion depends on the way a problem was framed. Prompt Invariance compares original, blind, inverted and adversarial formulations while keeping the evidence structure controlled.
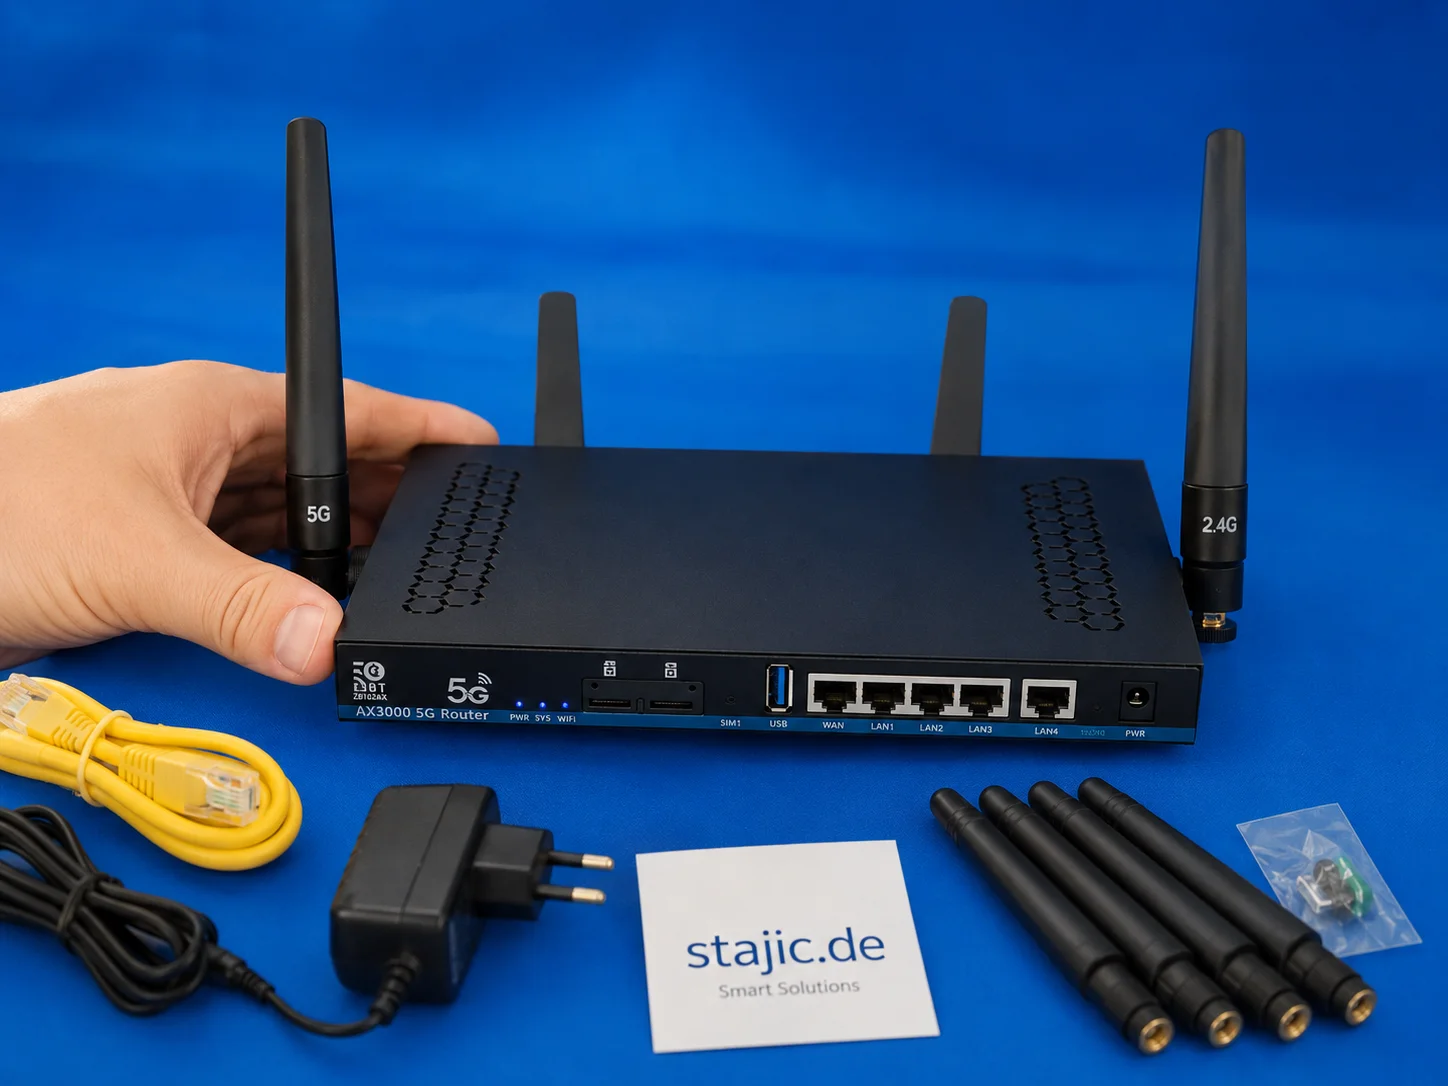
ZBT Z8102AX 5G OpenWrt Router Review: Dual SIM, RM500U-EA and an Honest Assessment
The ZBT Z8102AX is an unusual 5G router with an OpenWrt base, a dual-SIM concept, and a Quectel RM500U-EA modem. In testing, it shows clear strengths in flexibility, interfaces, and mobile connectivity, but also the typical weaknesses of a vendor-modified OpenWrt build.
Comprehensive Metrics Guide for Delivery and Change Management
This guide provides a detailed overview of essential metrics for enterprise delivery and change management, helping teams measure performance, optimize processes, and drive continuous improvement. Discover key indicators, calculation methods, and best practices to align your metrics with business outcomes.