
Ultimate Guide to Acceptance Criteria for LLM Adoption in Enterprise Playbooks
Ultimate Guide to Acceptance Criteria for LLM Adoption in Enterprise Playbooks
Introduction to Acceptance Criteria
Acceptance criteria (AC) are the definitive conditions that must be met for a feature, user story, or project deliverable to be considered complete. In the context of LLM (Large Language Model) adoption within enterprise playbooks, AC serve as the backbone for measuring success, mitigating risks, and ensuring alignment across technical, operational, and business teams.
Unlike vague requirements, AC are specific, testable, and binary: either met or not met. They bridge the gap between high-level objectives and granular implementation, which is particularly important for complex AI integrations where outputs can be probabilistic and difficult to validate without clear rules.
Why Acceptance Criteria Matter for LLM Adoption
- Risk Reduction: LLMs introduce variability in outputs; clear AC reduce scope creep and deployment failures.
- Stakeholder Alignment: Ensures product owners, developers, QA teams, and executives share a common understanding.
- Measurable Progress: Enables iterative development in agile playbooks.
- Compliance and Governance: Critical for enterprises handling sensitive data under regulations such as GDPR, HIPAA, or sector-specific governance rules.
Key Principles for Writing Effective Acceptance Criteria
Follow these foundational principles to craft AC that move LLM projects forward:
- Specificity: Use concrete language and avoid ambiguity, for example “95% accuracy on the approved test set” instead of “good performance”.
- Testability: Each criterion must be verifiable through automated tests, manual checks, evaluation datasets, or measurable metrics.
- Independence: Criteria should stand alone without hidden dependencies on other criteria.
- Comprehensiveness: Cover functional behavior, non-functional requirements, edge cases, and failure modes.
- Prioritization: Distinguish between must-have, should-have, and nice-to-have criteria, for example using MoSCoW or Gherkin-style definitions.
Standard Formats for Acceptance Criteria
1. Gherkin (BDD) Format
Gherkin is useful for LLM playbooks because it is readable for business stakeholders and compatible with behavior-driven development workflows.
Example for LLM Query Response:
Given a user inputs a financial analysis query
When the LLM processes it with approved enterprise data
Then the response must:
- Contain no unsupported claims in the approved evaluation set.
- Achieve >90% semantic similarity to the validated ground truth answer where applicable.
- Respond in under 5 seconds.
- Redact PII automatically according to the configured policy.
2. Checklist Format
Checklist-based AC are simple and effective for quick validation, especially during PoC and pilot phases.
Example for LLM Fine-Tuning:
- Model perplexity reduced by 20% post-fine-tuning.
- Bias score <0.05 across defined demographic test sets.
- Inference cost per query <$0.01.
- 99.9% uptime in staging environment.
3. Rule-Based Format
Rule-based AC are useful for complex enterprise scenarios where automated routing, risk controls, or human review paths are required.
Rule: IF query contains proprietary data AND confidence score <0.8 THEN route to human reviewer ELSE auto-approve.
Acceptance Criteria Templates for LLM Adoption Stages
Stage 1: Proof of Concept (PoC)
At the PoC stage, acceptance criteria should focus on feasibility and controlled validation.
- LLM generates responses matching 80% of benchmark test cases.
- Integration with internal APIs succeeds in 95% of calls.
- Data privacy scan passes with zero detected leaks in the test environment.
- Team conducts demo with <5% unresolved critical questions.
Stage 2: Pilot Deployment
At the pilot stage, AC should emphasize scalability, user feedback, operational readiness, and controlled exposure.
- 100 concurrent users supported with <2s average latency.
- User satisfaction score >4/5 from 50+ surveys.
- Custom RAG retrieves relevant documents in top-3 results 85% of the time.
- Rollback procedure tested successfully twice.
Stage 3: Full Production Rollout
At production stage, acceptance criteria must prioritize robustness, governance, reliability, and measurable business impact.
- Cost per 1K tokens remains below the defined enterprise threshold.
- A/B test shows 25% productivity uplift against the agreed baseline.
- Automated monitoring alerts on drift or anomalies within 1 minute.
- Compliance audit completed with documented findings and remediation status.
Practical Steps to Define and Implement AC
- Collaborate in Refinement Sessions: Involve LLM engineers, domain experts, QA, product owners, and end users in focused workshops.
- Map to Business KPIs: Link AC to metrics such as time-to-insight, error reduction, support resolution speed, or cost control.
- Leverage Tools: Use Jira or Confluence for documentation, LangSmith or Weights & Biases for LLM tracing, and Prometheus or Grafana for performance monitoring.
- Test Early and Often: Integrate AC into CI/CD pipelines with prompt tests, retrieval tests, output checks, and evaluation datasets.
- Review and Iterate: Use post-sprint retrospectives to refine AC based on observed behavior and stakeholder feedback.
- Document Edge Cases: Explicitly define behavior for hallucinations, bias risks, out-of-domain queries, adversarial prompts, and insufficient context.
Common Pitfalls and How to Avoid Them
- Overly Rigid AC: Balance precision with flexibility for AI's probabilistic nature. Use thresholds and evaluation datasets, not unrealistic absolutes.
- Ignoring Non-Functional Requirements: Always include security, performance, observability, compliance, and maintainability.
- Neglecting User Personas: Tailor AC to roles. Executives may need concise summaries; analysts may need detailed traces and citations.
- Scope Creep: Use the MoSCoW method — Must, Should, Could, Won't — to prioritize.
| Pitfall | Symptom | Fix |
|---|---|---|
| Vague Metrics | “Fast enough” | Define: <3s p95 latency. |
| No Failure Modes | Assumes perfect inputs | Add graceful handling of adversarial prompts and insufficient context. |
| Team Misalignment | Disputes in demos | Require pre-signoff by stakeholders before implementation. |
Real-World Examples from Enterprise LLM Playbooks
Case Study: Customer Support Automation
User Story: As a support agent, I want the LLM to triage tickets so I can focus on high-value cases.
Acceptance Criteria:
- Classify ticket urgency with 92% F1-score.
- Suggest 3 resolution steps with citations.
- Escalate 10% of cases to humans accurately based on predefined routing rules.
- Audit log every interaction for compliance.
Outcome: 40% faster resolution and 15% CSAT increase.
Case Study: Internal Knowledge Retrieval
User Story: As a new hire, I want to query internal documentation via LLM for onboarding.
Acceptance Criteria:
- Retrieve from 10K+ documents with 88% recall@5.
- Handle multilingual queries.
- Block queries on confidential sections based on access rights.
- Feedback loop improves retrieval and answer quality weekly.
Measuring Success Beyond AC
Acceptance criteria are checkpoints, not endpoints. After rollout, enterprise teams should track longitudinal metrics:
- Adoption Rate: Percentage of the workforce actively using LLM tools.
- ROI: (Value Created - Costs) / Costs.
- Model Health: Drift detection, A/B testing, latency, error rates, and regression results.
Regularly audit and evolve playbook acceptance criteria to adapt to LLM advancements such as multimodal models, agentic workflows, stronger retrieval systems, and changing compliance requirements.
Conclusion
Robust acceptance criteria transform LLM adoption from experimental activity into enterprise-grade delivery. By embedding AC into playbooks, teams create reliable checkpoints for quality, governance, security, performance, and business value.
Start with templates, test against real workflows, iterate relentlessly, and treat AC as a living control mechanism for enterprise AI adoption.
Related Articles

Should You Buy a 5G OpenWrt Router with Old Firmware? ZBT Z8102AX as a Practical Example
Buying a 5G OpenWrt router with older firmware can make sense, but only under the right conditions. The ZBT Z8102AX shows both sides clearly: the hardware is useful, the modem works, and the router stayed stable in testing, but OpenWrt 21.02, weak packaging and unclear upgrade paths require a careful buying decision.
Database Marketing – Modern Approach for Customer Relationships
Modern overview of database marketing: from data strategy and technical architecture to automation, GDPR and best practices for sustainable customer relationships.
ZBT Z8102AX OpenWrt 21.02 Firmware Review: Stable Enough, but Is It Future-Proof?
The ZBT Z8102AX runs a vendor-modified OpenWrt 21.02 build with kernel 5.4.246. In practical testing, the firmware worked successfully and kept the router stable for several days, but the old base raises important questions about security, modem control, upgrade paths and long-term maintainability.
Comprehensive Guide to Rollback Triggers in Enterprise AI Runbooks
This guide explores Rollback Triggers, essential mechanisms in enterprise AI runbooks that automatically detect anomalies and initiate rollbacks to maintain system stability. Learn how to configure, monitor, and optimize these triggers for robust AI deployments.

AI Agent Memory Is Not RAG: How to Separate Memory, Retrieval, State and Context
Agent memory, RAG, state, and context are often used as if they were interchangeable. They are not. This practical architecture model separates the four layers, shows where each belongs, and explains what breaks when systems collapse them into one.

Why More Context Can Make AI Answers Worse
A larger context window does not guarantee a better answer. This article explains how signal dilution, conflicting evidence, stale state, position sensitivity, and lossy compression can reduce AI reliability—and introduces a practical Context Pressure Test.
Emerging Linux Trends in 2026: Shaping the Future of Server Infrastructure
Explore the key Linux trends of 2026, from Kubernetes dominance and immutable distributions to AI integration and eBPF security.
Streamlining Code Quality: Testing with ESLint and Prettier
This article details the integration of ESLint and Prettier into modern development and testing workflows, focusing on practical implementation for consistent code quality and style.
HEIC to JPG Conversion: Why You Should Consider It and How It Works
HEIC offers modern image compression and high quality, but JPG remains the most compatible format. This guide explains when and how to convert HEIC to JPG using Linux tools and automation.

Migrating from OpenAI Agents SDK to the Agents API: What Actually Changes Architecturally?
Migrating from the OpenAI Agents SDK to the new Agents API is not an import rename. The runtime boundary changes: the agent loop, durable session, orchestration, context compaction and recovery move toward a managed harness. This guide shows what should move, what should stay in your application, and how to prove the migration before cutover.
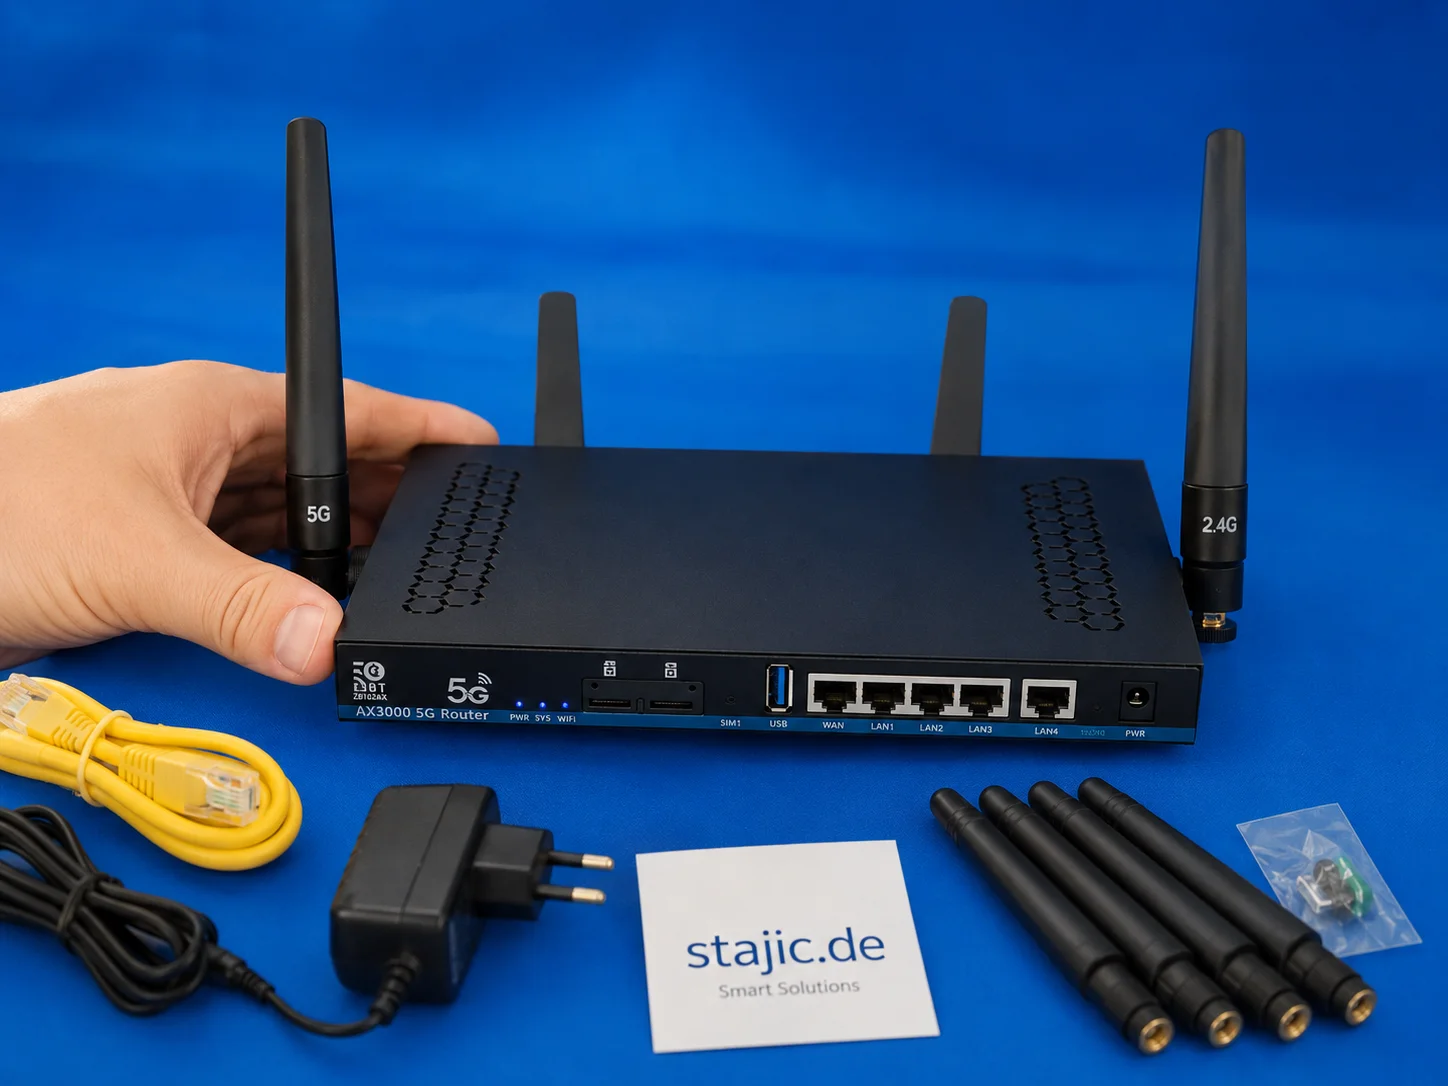
ZBT Z8102AX 5G OpenWrt Router Review: Dual SIM, RM500U-EA and an Honest Assessment
The ZBT Z8102AX is an unusual 5G router with an OpenWrt base, a dual-SIM concept, and a Quectel RM500U-EA modem. In testing, it shows clear strengths in flexibility, interfaces, and mobile connectivity, but also the typical weaknesses of a vendor-modified OpenWrt build.

What Is RAG? The Simplest Explanation of How It Works
RAG sounds complicated, but the idea is simple: before an AI answers, it first looks up useful information from a knowledge source and gives that information to the language model. This guide explains RAG, LLMs, state, memory and tools using one simple mental model.