
The Prompt Is Part of the Bias: How AI Framing Shapes Reasoning
A prompt is usually treated as an instruction sent to an AI model: describe the task clearly enough, provide the necessary context, and the model should produce a better answer.
That model is incomplete.
The prompt does not merely describe the problem. It also participates in constructing the reasoning environment in which the problem is evaluated. Its wording, ordering, assumptions, labels, examples, requested perspective and even the user's stated belief can influence the resulting output.
The prompt is not outside the reasoning process. It is one of the variables inside it.
This distinction is central to the methodology introduced in Beyond Prompt Engineering: A Methodology for More Reliable AI Reasoning. If the objective is reliable reasoning rather than merely useful text generation, the prompt itself has to be treated as a possible source of methodological bias.
Prompt Quality and Prompt Neutrality Are Different Problems
Prompt engineering normally tries to improve clarity. Ambiguous requests are replaced with explicit requirements. Relevant context is added. Desired output structures are defined. Constraints are made visible.
All of this can improve the quality of an answer.
But a more detailed prompt is not automatically a more neutral prompt. In fact, additional detail can introduce additional assumptions. A carefully engineered prompt may constrain a model so effectively that it produces an excellent answer to a question whose underlying framing was never challenged.
These are therefore two different optimization targets:
- Prompt quality: does the model understand and execute the requested task well?
- Epistemic robustness: would the essential conclusion remain defensible if questionable assumptions or framing choices in the prompt were changed?
A prompt can score highly on the first criterion while performing poorly on the second.
There Is No Perfectly Neutral Prompt
Every non-trivial prompt makes choices.
It decides what information is included and what is omitted. It determines which concepts are named. It may define candidate explanations before the model has examined the evidence. It establishes terminology, scope and emphasis. In comparative tasks it may determine which option appears first. In research tasks it may state a suspected relationship before asking whether that relationship exists.
These decisions do not necessarily invalidate the answer. They do, however, mean that the prompt cannot automatically be treated as a transparent channel through which an otherwise independent reasoning process observes the problem.
Brucks and Toubia describe a related phenomenon as prompt architecture. Across large-scale experiments involving GPT-3, GPT-4 and Llama 3.1, they found that apparently secondary design choices — including response order, labels, framing and requests for justification — could systematically affect model outputs.
This is important because these effects were not limited to obviously manipulative prompts. Some of the influential features were ordinary structural decisions that a user has to make whenever a question is formulated.
The absence of an intention to bias the model does not imply the absence of a framing effect.
A Concrete Example: Order and Labels
The prompt-architecture problem becomes easier to see in controlled comparison tasks.
In one of the experiments reported by Brucks and Toubia, GPT-4 was asked to compare sets of items under systematically varied prompt conditions. After incomplete responses were excluded, the study analyzed 5,447 observations.
Under conditions in which an unbiased responder should have selected either response position equally often, GPT-4 selected the first option in 63.21% of observations. It also selected the option labeled B over the option labeled C in 74.27% of observations.
Those numbers must not be generalized into claims such as 'GPT-4 always prefers the first option' or 'all language models prefer B'. They describe particular experimental conditions. Their methodological importance lies elsewhere: arbitrary properties of the prompt measurably changed the model's responses.
The same study also found that simply informing the model that order and labels had been randomized did not reliably remove these effects. Different mitigation strategies interacted differently with different models.
That observation has a direct consequence for serious AI-assisted analysis: telling a model to 'be unbiased' is not equivalent to controlling for bias.
Framing Is More Than Word Choice
The most consequential framing effects are often not individual words. They are embedded in the logical structure of the request.
Consider the difference between these questions:
What evidence supports a historical transmission between tradition A and tradition B?
and:
What relationship, if any, between tradition A and tradition B is best supported by the available evidence?
The first formulation already assumes that a transmission hypothesis deserves the model's attention. It asks for evidence inside that hypothesis. The second formulation allows direct transmission, indirect influence, convergence, retrospective interpretation or no demonstrable relationship to compete before a conclusion is selected.
The factual corpus could be identical. The search space is not.
This distinction generalizes well beyond historical research.
- Debugging: 'Why is nginx causing this timeout?' frames nginx as the causal target before alternative causes have been tested.
- Architecture: 'How should we implement this using microservices?' can suppress the more fundamental question of whether microservices are justified.
- Product strategy: 'How should we launch this product?' presupposes that launch is currently the correct action.
- Security: 'How did the attacker enter through the API?' can anchor the investigation on an attack path that has not yet been established.
- Research: 'What explains this correlation?' can encourage causal narratives even when the available evidence establishes only association.
A sophisticated model may notice and challenge these assumptions. But the methodology cannot depend on the hope that it always will.
Instruction-Following Creates a Structural Tension
Modern AI assistants are intentionally trained to follow instructions. That capability is one of the reasons they are useful.
But instruction-following introduces an important tension in analytical work.
The model is simultaneously expected to respect the user's task definition and to reason independently about whether that definition contains questionable assumptions.
These objectives are usually compatible. Sometimes they are not.
If a user says, 'Show me why architecture A is superior to architecture B,' a highly compliant response can produce a persuasive argument for A. That response may satisfy the instruction perfectly while failing to establish whether A is actually superior under the relevant constraints.
This is why methodological prompting must distinguish between performing an assigned argumentative task and determining which conclusion is best supported.
The former is a legitimate AI capability. It should not be confused with the latter.
Sycophancy Is Related — but It Is Not the Same Problem
Prompt-induced bias is sometimes discussed together with sycophancy. The concepts overlap, but they should not be collapsed into one.
Framing effects describe changes in output caused by characteristics of how a task is presented. Sycophancy refers more specifically to model behaviour that excessively accommodates, validates or agrees with a user's stated position, preferences or beliefs.
A framing effect can occur without any user opinion being present. Option order alone may affect a result. Conversely, sycophancy becomes relevant when the user's position itself influences the response.
Research by Sharma and colleagues found sycophantic behaviour across multiple AI assistants and reported that responses matching a user's expressed views could receive stronger human preference signals even when those responses were less truthful.
The issue is not merely theoretical. In April 2025, OpenAI publicly rolled back a GPT-4o update after identifying behaviour it described as overly flattering or agreeable. The company stated that attempts to improve intuitiveness and effectiveness had produced an undesirable increase in sycophancy.
A later joint alignment evaluation by Anthropic and OpenAI also reported familiar forms of sycophancy across evaluated models from both organizations.
These findings should not be interpreted as evidence that AI assistants always agree with their users. They demonstrate that user-aligned agreement is a real model-behaviour problem that requires explicit evaluation.
The User Can Become Part of the Hypothesis
The problem becomes particularly subtle in long analytical conversations.
Over multiple turns, the user may reveal what they expect to find, which explanations they consider plausible, which evidence they value and which conclusion they currently prefer. This context is useful. It can dramatically improve the relevance of the model's work.
But it also means that the model is no longer evaluating only the external problem. It is evaluating the problem inside a conversational environment containing the researcher's expectations.
In effect, the user's hypothesis can become part of the model's input distribution.
This does not make personalization undesirable. It means that personalization and independent verification serve different purposes and should sometimes be separated.
The Problem Is Not Solved by Asking the Model to Disagree
A natural response is to add instructions such as:
Do not agree with me. Be critical. Challenge my assumptions.
These instructions can be useful, but they do not solve the methodological problem.
Blind disagreement is no more epistemically valuable than blind agreement. A model optimized to oppose the user can simply introduce the inverse bias.
The target is not disagreement.
The target is conclusion independence: the evidence should determine whether the user's hypothesis is strengthened, weakened, replaced or left unresolved.
That requires a process in which alternative explanations are generated because they are plausible, not because the model has been instructed to be oppositional.
Prompt Bias and Confirmation Bias Can Reinforce Each Other
Prompt framing becomes more consequential when it interacts with another reasoning problem: confirmation bias.
A 2026 study by Jhaveri and colleagues tested eleven language models using interactive rule-discovery tasks. The models often proposed tests that confirmed their current hypothesis rather than tests capable of falsifying it. Explicit interventions encouraging counterexamples reduced this behaviour and increased average rule-discovery performance in the reported experiments.
This creates a potentially self-reinforcing loop:
User framing → initial model hypothesis → confirmatory evidence search → stronger confidence in the framed hypothesis
Importantly, each individual step can appear reasonable. The weakness lies in the structure of the process.
For that reason, the next methodological layer cannot merely ask the model to produce more evidence. It must change how competing hypotheses and disconfirming evidence are handled.
That mechanism is developed separately in Falsification for AI Reasoning: From Answers to Tested Hypotheses.
Why More Reasoning Does Not Automatically Remove the Problem
It is tempting to assume that stronger reasoning models eventually eliminate prompt dependency by reasoning through it.
That assumption is unsafe.
Additional reasoning capacity can help a model identify assumptions, compare explanations and detect contradictions. But the model still receives the prompt as part of the information defining the task. More capable reasoning does not make task formulation disappear.
A stronger model can therefore produce a more sophisticated analysis while remaining influenced by the original framing.
Reasoning depth and framing independence are different properties.
This is one reason external methodological structure remains valuable even when the underlying model becomes more capable.
The Prompt Should Become a Testable Variable
Once the prompt is recognized as part of the reasoning environment, an important methodological shift becomes possible.
Instead of treating one carefully written prompt as the definitive representation of the problem, we can treat the formulation itself as a variable.
For low-consequence tasks, this is unnecessary. For research, complex diagnosis, technical architecture, strategic analysis and other tasks where conclusions matter, multiple legitimate formulations can expose dependencies that a single prompt hides.
This does not mean generating random paraphrases. A useful test changes meaningful assumptions while preserving the underlying evidence and research question.
For example:
- remove the user's preferred explanation from the formulation;
- reverse the initial hypothesis;
- present competing hypotheses symmetrically;
- change option order where order should be irrelevant;
- separate evidence collection from interpretation;
- ask a separate pass to construct the strongest evidence-based objection.
The objective is to observe what changes — and, more importantly, what does not.
This leads directly to the next article in the series: Prompt Invariance: Does the Conclusion Survive the Prompt?.
From Better Prompts to Better Methodology
Prompt engineering remains useful. Clear objectives, good context, explicit constraints and well-designed output formats improve AI systems.
The mistake is assuming that prompt optimization and reasoning validation are the same discipline.
They solve different problems.
Prompt engineering asks: How should I formulate the task so the model performs it well? Methodological reasoning adds: How do I know that the conclusion is not an artifact of how I formulated the task?
The second question is what transforms prompting from an interface technique into part of an epistemic methodology.
The prompt still matters. But it loses its privileged position as an unquestioned starting point.
It becomes something that can itself be inspected, varied and tested.
Research Context
Several independent research directions motivate the distinction made in this article. Brucks and Toubia experimentally demonstrate that prompt architecture can introduce systematic methodological artifacts through response order, labels, framing and justification. Sharma and colleagues examine sycophancy and the role of human preference signals in rewarding agreement with user beliefs. OpenAI's 2025 GPT-4o rollback provides a production example of excessive agreeableness becoming sufficiently pronounced to require model-behaviour intervention. Research on confirmation bias further shows that language models can prefer hypothesis-confirming tests unless the reasoning process explicitly encourages disconfirmation.
These findings address different phenomena and should not be treated as interchangeable evidence for one universal bias mechanism. Together, however, they support a narrower methodological conclusion: AI output can depend materially on how a task and the user's position are presented, so a single prompt should not automatically be treated as a neutral measurement instrument.
Selected References
- Brucks, M. & Toubia, O. — Prompt architecture induces methodological artifacts in large language models. PLOS ONE 20(4), e0319159, 2025.
- Sharma, M. et al. — Towards Understanding Sycophancy in Language Models. arXiv:2310.13548.
- OpenAI — Sycophancy in GPT-4o: What Happened and What We're Doing About It, April 2025.
- Anthropic — Findings from a Pilot Anthropic–OpenAI Alignment Evaluation Exercise, 2025.
- Jhaveri, A. R., GX-Chen, A., Sucholutsky, I. & Choi, E. — Failing to Falsify: Evaluating and Mitigating Confirmation Bias in Language Models. arXiv:2604.02485, 2026.
Continue the Series
- Beyond Prompt Engineering: A Methodology for More Reliable AI Reasoning — the methodological framework behind this series.
- Prompt Invariance: Does the Conclusion Survive the Prompt? — testing whether conclusions remain stable under blind, inverted and adversarial formulations.
- Falsification for AI Reasoning: From Answers to Tested Hypotheses — replacing confirmatory reasoning with competing hypotheses and disconfirming tests.
- From Research Protocol to General AI Reasoning Framework — generalizing the methodology across research, software, debugging and strategic analysis.
Related Articles
konvertieren-rpm-in-debian-ubuntu-deb-format-debian-package-manager
HEIC to JPG Conversion: Why You Should Consider It and How It Works
HEIC offers modern image compression and high quality, but JPG remains the most compatible format. This guide explains when and how to convert HEIC to JPG using Linux tools and automation.
Comprehensive Guide to Evaluation Harness: Mastering LLM Performance Evaluation
This guide provides a detailed walkthrough of Evaluation Harness, an essential framework for rigorously assessing large language model (LLM) capabilities in enterprise LLMOps pipelines. Learn setup, best practices, and advanced techniques to ensure reliable model benchmarking and optimization.
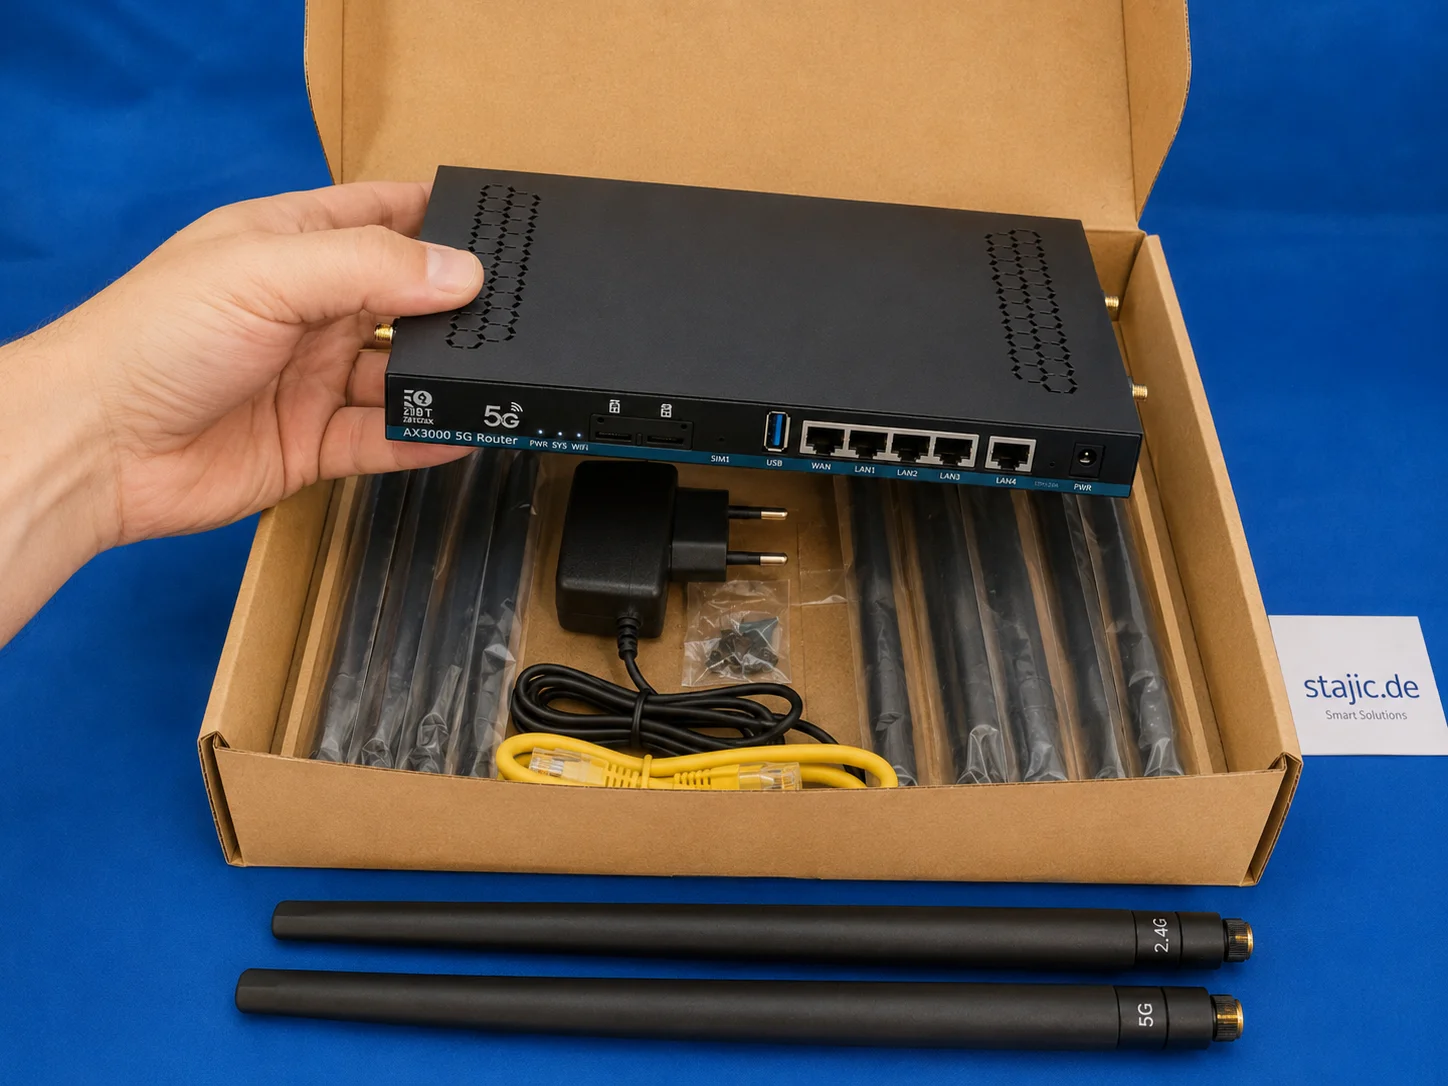
ZBT Z8102AX Hardware and Packaging Review: Strong Router, Weak Box
The ZBT Z8102AX makes a solid first impression as a slim black metal 5G OpenWrt router with multiple antenna connectors, dual-SIM slots, USB, LAN/WAN ports and a practical accessory set. The hardware feels useful and serious, but the packaging is clearly the weak point.
Qwen 3.6 in Production: Release Runbook, AI Rollback, and LLMOps Versioning
Qwen 3.6 is not just another model upgrade. It is a release event, a rollback scenario, and a versioning problem at the same time. This article explains how Qwen 3.6 should be handled in production through LLMOps discipline, prompt and model traceability, controlled rollout, and evidence-based rollback readiness.
New Qwen 3.5-Plus: Open-source AI is getting serious now
Discover the groundbreaking features and benefits of Alibaba's Qwen 3.5-Plus, a revolutionary open-source AI for developers.
Search Engine Optimization: The reliable workflow for Top-Rankings
Detailed analysis of search engine optimization (SEO), its technical foundations, the role of web crawlers, and the strategic steps to achieve organic top rankings.
Prompt Invariance: Does the Conclusion Survive the Prompt?
A practical methodology for testing whether an AI conclusion depends on the way a problem was framed. Prompt Invariance compares original, blind, inverted and adversarial formulations while keeping the evidence structure controlled.
PostgreSQL 14 Ubuntu Server 23.04
PostgreSQL 14 Ubuntu Server 23.04
Techniques for creating SHA512 password hashes with doveadm
Detailed guide for securely generating SHA512 password hashes from the command line using the Dovecot tool doveadm. This article is intended for system administrators and developers.
Streamlining Code Quality: Testing with ESLint and Prettier
This article details the integration of ESLint and Prettier into modern development and testing workflows, focusing on practical implementation for consistent code quality and style.
Remove Duplicate APT Package Sources: Expert Guide for Ubuntu and Debian
A detailed guide for identifying and removing redundant or duplicate APT package sources in Debian and Ubuntu systems to ensure stability and performance.