Enterprise Start Here: Your Gateway to Operational Excellence
Welcome to Enterprise: Start Here
If you're new to our enterprise platform or looking to optimize your operations, you've arrived at the right place. The Start Here hub serves as your comprehensive onboarding center, guiding you through proven frameworks, tools, and processes tailored for enterprise-scale deployments. Whether you're a C-suite executive, IT leader, or operations manager, this page outlines a clear path to leverage our resources effectively.
Why Start Here?
Enterprise environments demand reliability, scalability, and efficiency. Our platform addresses these needs with battle-tested components that reduce implementation time, minimize risks, and drive measurable outcomes. Starting here ensures you build on solid foundations rather than reinventing processes from scratch.
Success in enterprise operations begins with the right blueprint—not trial and error.— Enterprise Operations Principle
Your Structured Onboarding Path
Follow this sequential path to maximize value. Each step builds on the previous, integrating seamlessly across our ecosystem.
- Review Reference Models to understand industry-standard architectures and best practices.
- Dive into Playbooks for step-by-step strategies on common enterprise scenarios.
- Implement with Runbooks for precise, repeatable execution of critical procedures.
- Measure progress using Assessments to benchmark and refine your operations.
Step 1: Explore Reference Models
Reference models provide blueprints for enterprise architectures, covering areas like cloud migration, security postures, and DevOps pipelines. These models are derived from real-world deployments across Fortune 500 companies, ensuring applicability without customization overhead. Begin here to align your strategy with proven patterns.
Step 2: Master Playbooks
Playbooks translate high-level strategies into actionable guides. From incident response to scaling infrastructure, each playbook includes decision trees, checklists, and integration points with your existing tools. Use them to orchestrate complex initiatives with confidence.
Step 3: Execute with Runbooks
Runbooks are your tactical execution manuals. Designed for on-demand use, they detail exact commands, API calls, and troubleshooting flows. Ideal for 24/7 operations teams, runbooks ensure consistency and speed during high-pressure situations.
Step 4: Evaluate with Assessments
Assessments offer objective scoring frameworks to gauge maturity levels against benchmarks. Run self-assessments or guided audits to identify gaps, prioritize improvements, and track ROI over time.
Best Practices for Getting Started
- Assemble a cross-functional team including IT, security, and business stakeholders.
- Set clear KPIs aligned with your reference model selections.
- Pilot one playbook in a non-production environment before full rollout.
- Schedule quarterly assessments to maintain momentum.
- Leverage our community forums for peer insights and support.
Ready to Take the Next Step?
This hub is your launchpad. Bookmark it and refer back as you progress. For personalized guidance, contact our enterprise success team. Transform your operations today—start with Reference Models.
Related Articles
Fedora 43上的ComfyUI:双虚拟环境 + 一键启动(2026年3月)
目标:保留两个Python虚拟环境(例如3.12和3.14)以确保兼容性,但通过一个简洁、轻量的配置自动启动ComfyUI。
主权人工智能:模型、数据、基础设施与依赖关系的控制
主权人工智能关乎对模型、数据、基础设施、软件、运营和战略依赖的有效控制——而不仅仅是人工智能模型托管在哪里。
企业AI运行手册中回滚触发器的全面指南
本指南探讨回滚触发器,这是企业AI运行手册中的关键机制,能自动检测异常并启动回滚以维持系统稳定。了解如何配置、监控和优化这些触发器,以实现稳健的AI部署。
什么是上下文工程?模型在回答之前接收到了什么
上下文工程负责设计 AI 模型在推理前接收的信息,包括提示词、检索内容、记忆、应用状态、工具结果和对话历史。
LLM从哪里获取数据?Python中的RAG数据源
LLM 并不会神奇地知道你的文件、数据库或 API。这个 RAG 系列的实用续篇用简单的 Python 展示了外部数据如何变成可检索的证据:从文本文件和 SQL 到全文搜索、嵌入、上下文组装以及最终的 LLM 调用。
RBAC与租户隔离:两种不同的安全边界
RBAC 控制用户可以做什么;租户隔离控制该操作可以触及哪个租户的资源。了解为什么多租户 SaaS 安全需要这两道边界。
AI治理:模型、数据、权限、风险与可审计性
AI治理定义了在模型、提供商、数据、权限、风险、评估及整个生命周期中,谁可以批准、操作、更改和审计AI系统。
人工智能推理的可证伪性:从答案到经过检验的假设
AI模型几乎可以为任何看似合理的假设生成令人信服的证据。一种更可靠的方法论则提出相反的问题:什么证据会削弱、反驳或迫使我们放弃该结论?本文利用竞争性假设、判别性检验、反证和明确的拒绝标准,为LLM发展以证伪为导向的推理。
AI代理应该记住、遗忘、重新计算还是再次检索什么?
长时间运行的代理不应记住所有内容。本文提供了一个实用的生命周期模型,用于决定哪些内容应属于持久记忆、哪些内容应重新检索、哪些内容重新计算更安全,以及哪些内容应过期或被取代。
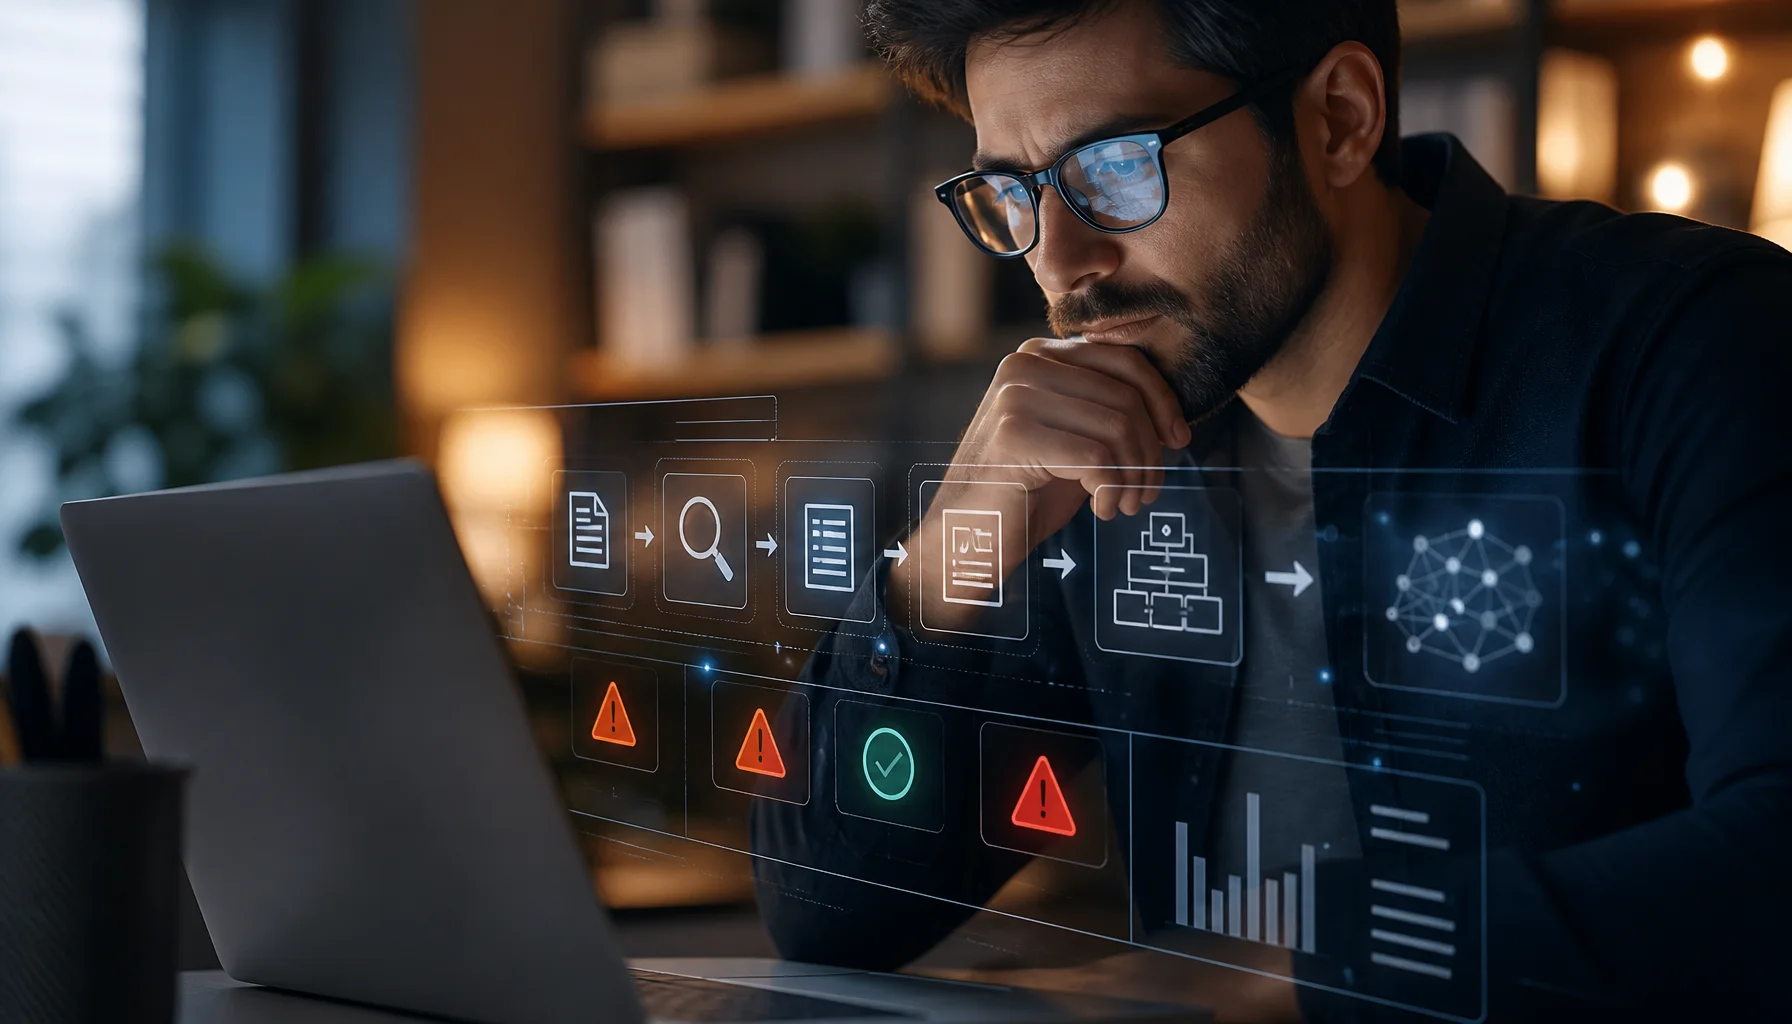
RAG失败了——但究竟是哪一层真正失败了?一种诊断方法
当RAG答案出错时,将问题归咎于检索或模型过于笼统。这种诊断方法将来源覆盖、查询构建、检索、排序、上下文组装、生成、证据归因和时效性逐一隔离,从而使实际故障能够被复现并修复。
2026年新兴Linux趋势:塑造服务器基础设施的未来
探索2026年Linux关键趋势:从Kubernetes主导地位与不可变发行版,到人工智能集成与eBPF安全技术。
向量数据库、嵌入和重排序:检索的三个不同部分
嵌入表示含义,向量数据库检索候选结果,重排序器则精炼结果。了解这三个检索层在RAG中如何不同并协同工作。